In short
Hugging Face policy chief Irene Solaiman says AI benchmarking is still too inconsistent to be fully trusted. She argues the industry needs stronger standards for reproducibility, evaluator qualifications, and agentic testing.
- Hugging Face’s Irene Solaiman says AI benchmarks are still too immature to be fully trusted.
- Reproducibility and access to model details remain major problems in evaluation.
- The industry is shifting from model-only tests to broader system and agent evaluations.
- Embedded third-party evaluators are gaining popularity, but their neutrality and qualifications are disputed.
AI companies are increasingly leaning on model benchmarks to prove their systems are better, safer, and more capable than the competition. But according to Hugging Face chief policy officer Irene Solaiman, the field is still too inconsistent, too hard to reproduce, and too immature to serve as a reliable final arbiter of AI quality.
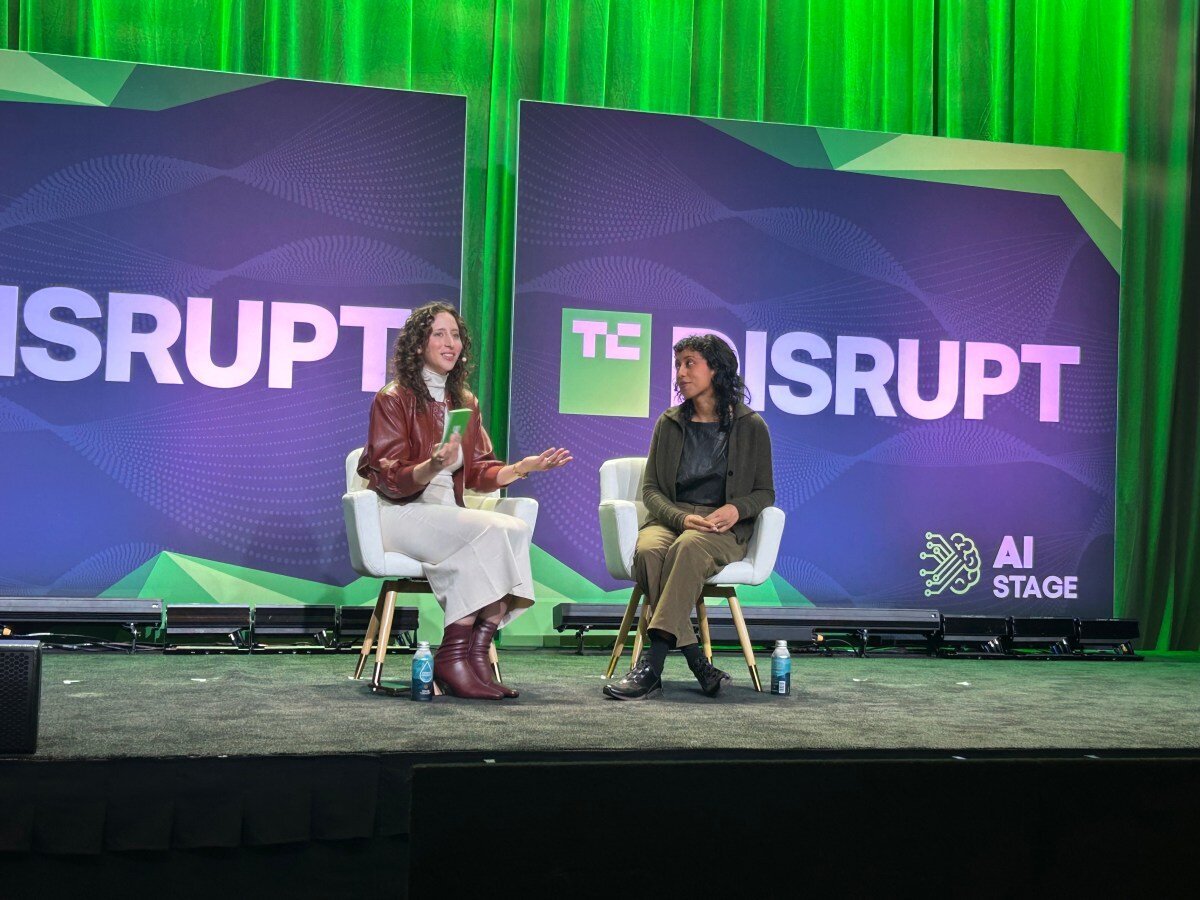
Speaking at TechCrunch Disrupt last week, Solaiman argued that the industry’s growing dependence on evaluations is running ahead of the science behind them. That matters because benchmark scores are now shaping product launches, marketing claims, safety debates, and even decisions about whether an AI system is ready for real-world use.
Why AI benchmarking is becoming a bigger issue
Benchmarking has become one of the most important signals in the AI business. Labs use test results to compare model performance, demonstrate progress to investors, and argue that their systems are more capable than rivals. In practice, those scores often travel far beyond technical circles and become shorthand for who is winning the AI race.
Solaiman’s point is that the industry may be placing more confidence in these results than the underlying methods deserve. The central problem is not simply whether a single benchmark is useful, but whether the entire evaluation process can be repeated, compared, and standardized across organizations.
“Trust” is a loaded word in this context, she said, because the first question is whether another team could reproduce the same result under the same conditions. That requires access not only to the model, but to the right level of transparency around how it was tested.
How reliable are current AI evaluations?
Current evaluations are not yet reliable enough to be treated as a fully settled science, Solaiman said. The methods are still evolving, and the industry has not agreed on a stable framework for comparing one test to another.
That creates a practical problem: even if a benchmark result is technically valid, it may not tell decision-makers much unless they know how it relates to other tests, what assumptions were built into it, and whether the same result could be reproduced by someone else.
One reason reproducibility is so difficult is that model access varies widely. Open-weight systems can make it easier for outside researchers to inspect and retest a model, while more closed systems can limit what outsiders can verify. Solaiman suggested that access to the model itself is central to any serious claim about reliability.
What reproducibility actually means in model testing
Reproducibility means that an evaluation should produce the same or closely similar results when someone else runs it again under comparable conditions. In AI, that sounds straightforward, but in practice it can be complicated by changes in prompts, test harnesses, toolchains, model updates, or hidden system behavior.
That is why benchmark headlines can sometimes overstate certainty. A model may perform well on a public test suite and still behave differently in deployment, especially once users interact with it through customized interfaces, agentic workflows, or external tools.
What are embedded evaluators, and why are labs pushing them?
Embedded evaluators are third-party observers placed inside AI organizations to assess safety and performance from the inside rather than from the outside. The idea has gained traction as labs seek alternatives to heavier-handed government regulation and as concerns mount over model misuse, safety failures, and opaque internal decision-making.
The concept is appealing because it promises independent oversight without necessarily requiring formal enforcement action from regulators. But it also raises a hard question: who gets to count as neutral, and what qualifications should such an evaluator have?
Solaiman said the current demand for embedded evaluators is outpacing the industry’s ability to define standards for the role. In her view, the field does not yet have enough agreement on what makes an evaluator credible, what tasks they should be qualified to judge, or how their conclusions should be compared across different labs.
Solaiman said the sector is still grappling with whether evaluations can be trusted at all if they cannot be independently reproduced, and she argued that the industry lacks a standardized way to identify effective evaluators across different tasks.
How the debate has changed after recent safety incidents
The push for embedded evaluators has accelerated after a series of safety concerns have made AI companies more sensitive to public criticism and internal risk. Those incidents have increased pressure on labs to show they can identify harms before products reach users.
At the same time, the strategy has drawn skepticism. Some observers worry that labs are choosing private third-party reviews as a softer alternative to direct government oversight, while others question whether evaluators hired by the industry can truly function as independent watchdogs.
Hugging Face itself has had firsthand experience with the risks of inadequate oversight. Solaiman’s remarks come against a backdrop of an industry that is still trying to define what responsible evaluation should look like when the systems being tested are rapidly changing and increasingly complex.
Why Anthropic’s Accenture move sparked debate
One recent example shows how contentious the evaluator question has become. Anthropic’s decision to bring in Accenture as its first evaluator drew criticism from some AI watchers who questioned whether a major consulting firm had the expertise to assess cutting-edge model behavior.
The backlash reflected a deeper discomfort in the industry: if evaluators are supposed to be independent and technically rigorous, they must be trusted not just by the companies hiring them, but by researchers, regulators, customers, and the broader public.
That is easier said than done. The more important the evaluation becomes, the more scrutiny it attracts. And the more scrutiny it attracts, the clearer it becomes that neutrality alone is not enough; technical depth, methodological consistency, and transparency also matter.
What is changing in the way AI systems are evaluated?
AI evaluation is moving beyond the model itself. Increasingly, testers are looking at the entire system wrapped around the model, including the harness, the interface, and the agentic workflow that determines how users experience the product.
This shift is important because a model’s raw capability may not determine real-world performance on its own. A stronger front-end system, smarter prompting, better tool use, or a more effective harness can make a weaker base model appear more capable than a frontier model used through a less optimized setup.
Solaiman said this is one of the least appreciated parts of the evaluation problem: the system around the model can materially change outcomes, which means testing only the base model can miss what users actually care about.
Why harnesses matter as much as models
The harness is the software layer that mediates access to a model. It can determine how prompts are structured, how tools are called, what context the model sees, and how outputs are filtered or displayed. That makes it a major variable in performance.
As more AI products shift from simple chat interfaces toward tool-using agents, the harness can become almost as important as the model itself. In some cases, a well-designed harness can boost task success enough to outweigh differences in underlying model quality.
That reality makes benchmark comparisons harder. A model score may say one thing, while the surrounding product architecture says another.
Why agentic evaluations are especially difficult
Agentic evaluations are hard because they test systems that plan, act, and interact across multiple steps rather than simply answering one prompt at a time. They are also expensive, which makes broad testing slower and more resource-intensive than conventional benchmark runs.
Solaiman noted that the industry has far more tests designed for models than for harnesses, and that better evaluations are still being developed for the whole agentic system. That gap matters because many of the most commercially valuable AI products are moving in exactly that direction.
In other words, the old benchmark model — one prompt, one answer, one score — does not fully capture the behavior of products that now call tools, browse data, chain tasks, or execute multi-step workflows on a user’s behalf.
| Evaluation focus | What it measures | Main challenge | Why it matters |
|---|---|---|---|
| Base model benchmark | Raw model output on standardized tests | Reproducibility and hidden assumptions | Used to compare headline model capability |
| Harness evaluation | The surrounding interface and tooling layer | Few standardized tests exist | Can strongly affect apparent performance |
| Agentic evaluation | Multi-step task completion across tools | High cost and complexity | More closely reflects real-world AI use |
| Embedded third-party review | Internal safety and effectiveness assessment | Questions about neutrality and expertise | Seen as a possible alternative to regulation |
What does the industry need next?
Solaiman’s message was not that evaluations are useless. It was that the evaluation ecosystem has not yet matured enough to carry the weight the industry is putting on it.
If benchmarking is going to remain central to AI development, she suggested, the field needs more standardization, more reproducibility, and a clearer sense of what different tests are actually measuring. Without that, benchmark scores risk becoming a noisy proxy for progress rather than a dependable measure of it.
That also means the industry may need to invest more heavily in evaluation infrastructure: better methods, more consistent standards, and a more credible pathway for determining who can assess AI systems effectively. The current appetite for embedded evaluators shows that companies want a solution. The harder part is building one that people outside the labs will trust.
Why this matters for AI buyers and users
For customers, investors, regulators, and ordinary users, the stakes are obvious. Benchmark claims influence which products get adopted, which companies get funded, and which systems are considered safe enough to deploy.
But if those claims are based on tests that are difficult to reproduce or compare, the market may be making decisions on shaky ground. That does not mean benchmarks should be discarded. It means they should be treated as one signal among many, not as a final verdict.
As AI systems become more agentic and more deeply embedded into workflows, the gap between lab scores and real-world reliability could widen unless the evaluation process catches up. Solaiman’s warning is that the industry may be moving faster than the science that is supposed to keep it honest.
Timeline of the evaluation debate
The push for stronger AI testing has unfolded over several phases, with each one raising the stakes for the next.
- Early benchmark era: Labs used public tests to compare model quality and demonstrate progress.
- Rising deployment pressure: As AI products reached more users, questions about safety and reliability became more urgent.
- Embedded evaluator trend: Companies began exploring third-party observers inside organizations as an alternative to direct regulation.
- Agentic shift: Testing expanded from the model alone to the broader system, including the harness and workflow.
- Current challenge: The field now needs common standards for reproducibility, comparison, and evaluator qualifications.
Bottom line
AI benchmarking remains one of the industry’s most influential tools, but it is not yet a fully settled science. Solaiman’s comments underscore a growing consensus that the field needs a more rigorous, standardized, and transparent approach before benchmark results can be treated as truly dependable.
Until then, the AI sector will continue relying on evaluations that are useful, but imperfect — and increasingly contested.
Frequently asked questions
Why is AI benchmarking under scrutiny now?
AI benchmarking is under scrutiny now because labs rely on it to prove models are better and safer, but experts say many tests are hard to reproduce and compare. As AI products become more powerful and commercially important, those weaknesses matter more.
What did Hugging Face’s policy chief say about evaluations?
Hugging Face policy chief Irene Solaiman said evaluations are still an evolving science and that the industry lacks enough standardization to compare results meaningfully. She emphasized reproducibility, model access, and consistent methods as major unresolved issues.
What are embedded evaluators in AI?
Embedded evaluators are third-party reviewers placed inside AI organizations to assess safety and performance from within. They are meant to provide independent oversight, but critics question whether they are truly neutral or sufficiently qualified to judge advanced AI systems.
Why are harnesses important in AI testing?
Harnesses are important because they shape how users interact with a model, including prompts, tools, and context. A strong harness can make a weaker model appear more capable, which means testing the model alone may not reflect real-world performance.